

Open-weight models shift the upfront cost from inventing a frontier stack to downloading one. They do not remove the physics bill: every training step and inference token still turns silicon into heat and heat into electricity. Saudi HUMAIN’s Arabic model on MiniMax weights only works if Riyadh also secures gigawatts, chips, and cooling—the subject of assembled sovereign AI.
If you are trying to read Saudi Arabia’s AI push and keep asking where the power comes from, you are asking the right question. If you assume open weights make the problem mostly about downloading a file, you are looking at the wrong line item.
Open weights change who owns the recipe for a model. They do not repeal thermodynamics. A 428-billion-parameter mixture-of-experts system such as humain-m3—built on MiniMax-M3 weights and further trained on Arabic text, as Culled described in assembled sovereign AI—still needs GPUs, network, and megawatts for every hour it trains or serves traffic.
Two different costs: the tarball and the bill
Separate three layers:
1. Weights (information). Model parameters are data. An open-weight release lowers license friction and can skip years of redundant pre-training. Downloading weights costs bandwidth and legal compliance, not a perpetual utility bill.
2. Compute (capital). GPUs, HBM, racks, and fabs are depreciating assets. Export controls sit here—Washington approves advanced chips; Riyadh’s HUMAIN stack depends on that channel.
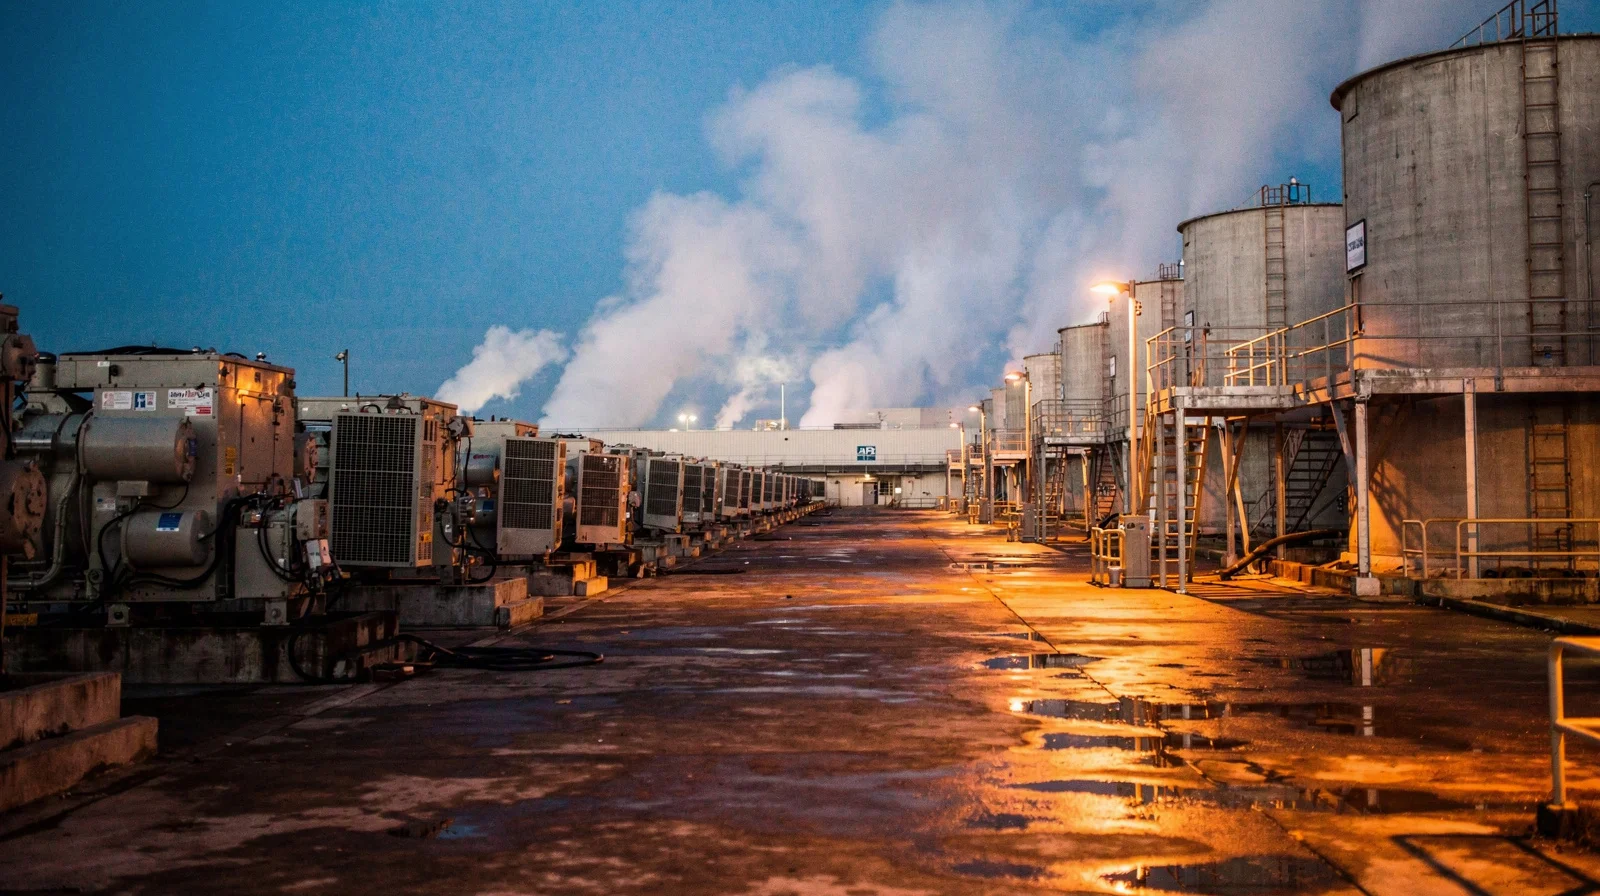
3. Energy (operations). Each floating-point operation draws power; power becomes heat; heat demands cooling. At scale, electricity and time-to-interconnect dominate operating economics, not the one-time copy of weights.
A rough training heuristic for dense transformers is on the order of six floating-point operations per parameter per token for backpropagation-heavy pre-training (the classic “6ND” scaling picture). Mixture-of-experts models activate only a subset of experts per token, so not every parameter moves on every forward pass—but Arabic continued pre-training on more than a trillion tokens still implies enormous aggregate FLOPs, hence enormous kWh.
Inference is the same physics at smaller per-query scale but never stops. Serving a frontier model to enterprises and developers is a continuous electricity and cooling draw, multiplied by batch size, sequence length, and utilization.
Weights answer what the model is. Megawatts answer whether you can run it at national scale.
That is why headlines about ~14 gigawatts reserved for HUMAIN’s AI factories (CEO Tareq Amin outlined the allocation in September reporting) belong in the same story as humain-m3—not as a footnote. Fourteen gigawatts is an order-of-magnitude statement about grid and generation allocation, comparable to a fleet of large reactors, not a laptop download.
Where Saudi power enters the stack
Reporting on HUMAIN’s 6 GW Riyadh campus describes the mundane sovereign layer: 380 kV substations, hundreds of megavolt-amperes of bulk supply, fiber, water, roads—the infrastructure that turns a desert plot into a addressable load for AI. MEED and trade press have tracked early contractor involvement on that campus.
Saudi Arabia’s advantage in this trajectory is not mystical. It is cheap capital, land, and energy policy plus willingness to assemble foreign layers: Chinese open weights, U.S. chips, local data governance. The weights travel as software; the substation does not.
None of that guarantees low marginal cost per token forever. Gas-linked power prices, turbine backlogs, and water for cooling still bite—as Culled argued when time-to-power became the scarce AI asset and when cooling and campus power sat ahead of model hype.
“Beam” is not the 14-gigawatt story
Search results mix two different Saudi narratives.
Beam AI (the enterprise agent vendor) announced a partnership with Saudi Arabia’s RDI to deploy agentic automation in local enterprises. That is software integration: workflows, APIs, governance—typically running on someone else’s cloud or rented GPU. It does not imply Beam owns a multi-gigawatt generation portfolio.
HUMAIN (PIF-backed full-stack AI) is the entity tied to humain-m3, hyperscale campuses, Nvidia/AMD/AWS infrastructure deals, and the 14 GW power conversation.
Confusing them makes the power question unanswerable. Beam asks who operates the agents; HUMAIN asks who owns the grid connection and the weight release.
Why open weights still matter—even when power is the bill
If electricity dominates at scale, why care about open weights at all?
Because middle powers optimize time and risk, not a physics textbook. Korea removed a national-model team for reusing Qwen weights; Riyadh treated the same pattern as acceleration—local Arabic data and deployment control on top of MiniMax. Open weights let governments skip rebuilding a frontier stack from zero while they spend years securing chips and gigawatts.
The strategic fork is dual:
- Beijing has debated restricting overseas access to the strongest open weights just as Riyadh built on them.
- Washington can tighten chip approvals if it views U.S. compute + Chinese bases as a loophole.
Open weights are therefore political currency as well as technical shortcuts—even though the operating invoice remains kilowatt-hours.
A reader’s checklist
When you see “sovereign AI on open weights,” ask five quantitative questions before treating weights as the cost center:
- How many active parameters per token (MoE routing), and what GPU-hours did continued pre-training require?
- What chip fleet is approved, and at what utilization?
- What megawatts are contracted—not announced—on the grid side?
- What PUE and cooling limit usable compute per megawatt?
- What license governs the weights after release, and can either supplier revoke the stack?
HUMAIN’s planned open-weight release of humain-m3 is the test case Culled flagged in October: the weights may become public, but the power contract and chip import path stay sovereign—and expensive.
The trajectory that matters for open-weight geopolitics is not “models are free.” It is models are portable; megawatts are not—and Saudi Arabia is betting it can buy portability from China while buying time on the grid at home.
Continue reading


Sources
HUMAIN humain-m3 launch materials (428B MoE, MiniMax-M3 lineage, planned open-weight release); Circuit and MEED reporting on ~14 GW power allocation and 6 GW Riyadh campus substation infrastructure; Culled saudi-assembled-sovereign-ai on Chinese weights and U.S. chips; Beam AI–RDI enterprise partnership announcements (agent deployment, not hyperscale power).


